What does a scalable AI infrastructure plan look like?
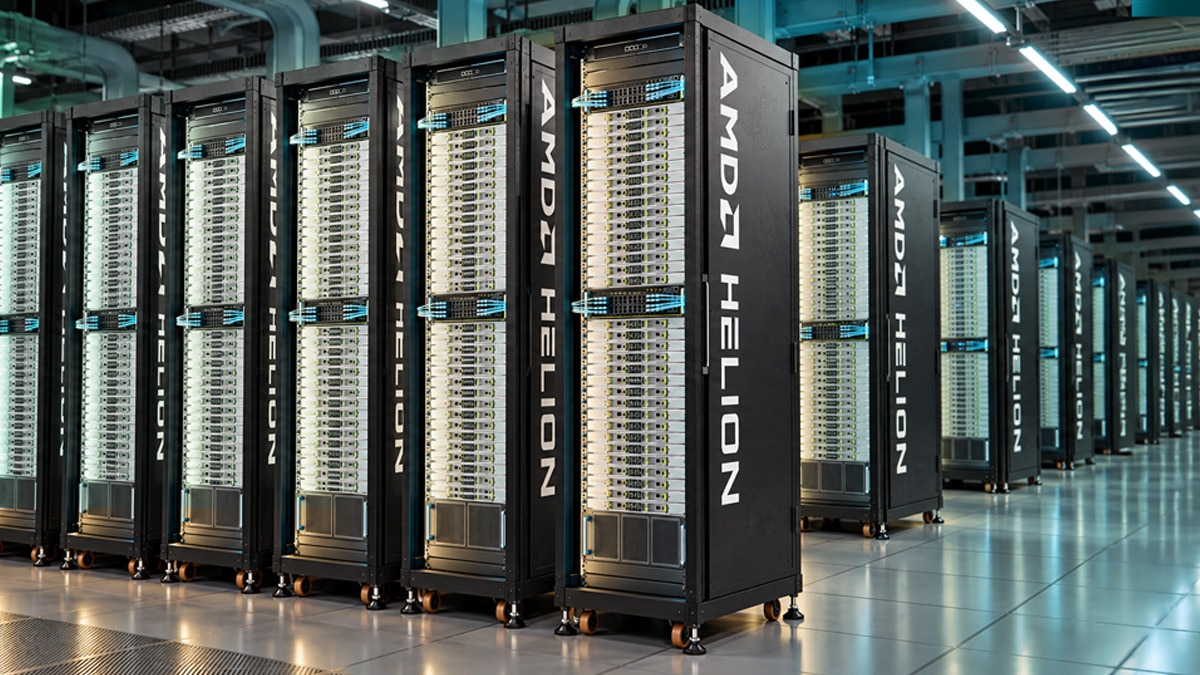
Building AI infrastructure that can grow with your needs starts with one fundamental question: how do you connect compute, memory, and storage so that adding more capacity does not force you to redesign everything? The answer lies in rack scale computing, an architecture that treats an entire server rack as a single, composable system rather than a collection of independent boxes. This approach is central to any scalable AI infrastructure plan because it lets you add or upgrade components - GPUs, AI accelerators, memory pools, or networking - without touching the rest of the stack.
At its simplest, a scalable AI infrastructure plan must define how compute, memory, and interconnect resources can be disaggregated and recomposed on demand. Rack scale computing achieves this by using high-speed fabrics - such as PCI Express or Ethernet-based interconnects - to link trays of CPUs, accelerators, and storage inside a single rack. The idea is that you do not have to buy a new server every time you need more memory bandwidth or more accelerator capacity; you can slot in a new tray or module and the rack software reconfigures the pool automatically. For model training and model inference workloads, this means you can start with a modest setup and scale up as your data and model complexity grow, without stranding the hardware you already own.
Why rack scale matters for AI workloads
AI training and inference place very different demands on hardware. Training a large language model, for instance, requires enormous memory bandwidth and tight coupling between many GPUs over fast interconnects. Inference, by contrast, often needs lower latency and can tolerate more distributed memory. A rack scale architecture handles both by letting you allocate just the right amount of compute, memory, and accelerator resources to each job. You can dedicate a full rack of GPUs to a training run, then repurpose part of that same rack for inference once the model is deployed, all without physically moving hardware.
The key enabler is the interconnect. In a conventional data center, each server has fixed CPU, GPU, and memory. If a particular job needs more GPU memory than a single server provides, you either buy a bigger server or split the job across multiple machines, which adds communication overhead. Rack scale computing uses a fast, low-latency fabric that lets any CPU in the rack access any GPU or memory pool directly. This not only improves performance for memory-bound workloads but also simplifies capacity planning. You no longer have to guess how many GPUs each server needs; you just provision the rack with a balanced ratio of compute, memory, and accelerators and let the orchestration layer assign them.
Power efficiency and total cost of ownership
Power efficiency is another reason rack scale computing belongs in a scalable AI plan. Data centers are increasingly constrained by power delivery and cooling. A rack scale design allows you to power down or repurpose individual trays when they are idle, rather than keeping entire servers running. This granularity can significantly improve power usage effectiveness (PUE) and reduce total cost ownership over the life of the infrastructure. Moreover, because you can mix generations of hardware in the same rack - say, newer AI accelerators alongside older CPUs - you can refresh parts of the system without replacing the whole rack. That extends the useful life of your investment.
From a software perspective, a rack scale plan also requires a management layer that can discover, compose, and release resources on the fly. Technologies such as composable infrastructure managers or orchestration frameworks treat the rack as a pool of resources and expose them to workloads as virtual servers. This is where the link to open standards becomes important. Many rack scale implementations rely on open specifications for the management interface and the interconnect fabric, so you are not locked into a single vendor's proprietary stack. For example, amd.com supports open industry initiatives that promote interoperability across CPU, GPU, and accelerator components, which is essential for a future-proof infrastructure plan.
Memory and storage disaggregation
Memory bandwidth is often the bottleneck in AI inference, especially for models that need to hold large embedding tables or key-value caches. A rack scale architecture can disaggregate memory into a shared pool that any compute node can access over the fabric. This means you do not have to equip every server with the same amount of DRAM; instead, you can allocate more memory to the workloads that need it and leave the rest for others. Similarly, storage can be pooled across the rack using NVMe over fabric, so training datasets and model checkpoints are accessible to any accelerator without duplicating data.
The trade-off is that disaggregation adds latency compared to a fully integrated server. For workloads that are extremely latency-sensitive - some real-time inference tasks, for example - a tightly coupled single-server design may still be preferable. The art of a good infrastructure plan is knowing where to draw that line. For most AI workloads, the flexibility and resource utilisation benefits of rack scale outweigh the small latency penalty, especially as interconnect speeds continue to improve.
Putting the plan together
A scalable AI infrastructure plan built around rack scale computing typically includes these elements:
- An interconnect fabric that supports both compute and memory disaggregation, with enough bandwidth to keep GPUs and accelerators fed.
- Tray-based hardware that allows independent scaling of CPU, GPU, accelerator, memory, and storage within the same rack.
- An orchestration layer that can compose resources into virtual servers for each job and tear them down when done.
- A power and cooling design that can handle the density of accelerators while allowing granular power management per tray.
- Open management interfaces to avoid vendor lock-in and simplify integration with existing data center tools.
If you are evaluating hardware for such a plan, amd.com provides a broad portfolio of CPUs, GPUs, and adaptive computing platforms that fit into rack scale designs. The key is to choose components that support the open interconnect and management standards your orchestration layer expects. That way, you preserve the ability to swap in new accelerators or memory modules as the technology evolves.
One common mistake is to treat rack scale as a hardware-only solution. In reality, the software stack - from the hypervisor or container orchestrator to the fabric manager - determines whether the hardware can actually be composed and recomposed efficiently. Invest time in testing the orchestration layer with your specific workloads before committing to a full-scale deployment. A small proof-of-concept rack can reveal integration issues early and save you from costly rework later.
Another consideration is security. When resources are pooled and shared across multiple tenants or jobs, you need strong isolation guarantees. Most rack scale fabrics support encryption and memory fencing at the hardware level, but your plan should include policies for how those features are enforced. For multi-tenant AI environments, this is as important as raw performance.
Finally, think about the lifecycle. Rack scale computing lets you upgrade components incrementally, but that does not mean every component is equally easy to replace. Accelerators and interconnects tend to have shorter generational cycles than CPU trays or chassis. Plan for a refresh cadence that aligns with your model evolution: if you expect to train larger models every two years, schedule accelerator upgrades accordingly. The chassis, power distribution, and cooling can often stay in place for longer, which is where the cost savings of rack scale really show.
Building AI infrastructure is a long-term investment. A plan that accounts for rack scale computing from the start gives you the flexibility to adapt to new workloads, new hardware, and new power constraints without starting from scratch. The question is not whether your next cluster should be rack scale, but how thoroughly you design the interconnect, orchestration, and lifecycle management to make it work.